About BioBuntu
An open-source bioinformatics platform built on principles of entity clarity, semantic data, and making advanced genomic analysis accessible to researchers worldwide.
Our Mission
To democratize advanced genomic analysis by providing researchers, labs, and bioinformatics professionals with a comprehensive, enterprise-ready platform that combines:
- Computational Excellence: RNA-seq, variant calling, metagenomics, and QC pipelines
- Multiple Interfaces: CLI, GUI, and Web Dashboard for Every Workflow
- Open-Source Philosophy: Community-driven, transparent, and freely available
Who We Serve
Research Labs
Genomics and bioinformatics research teams needing scalable pipelines
Educational Institutions
Universities teaching bioinformatics and computational biology
Bioinformaticians
Professionals requiring advanced analysis and automation tools
Biotech Companies
Organizations building on open-source bioinformatics infrastructure
Founder & Vision
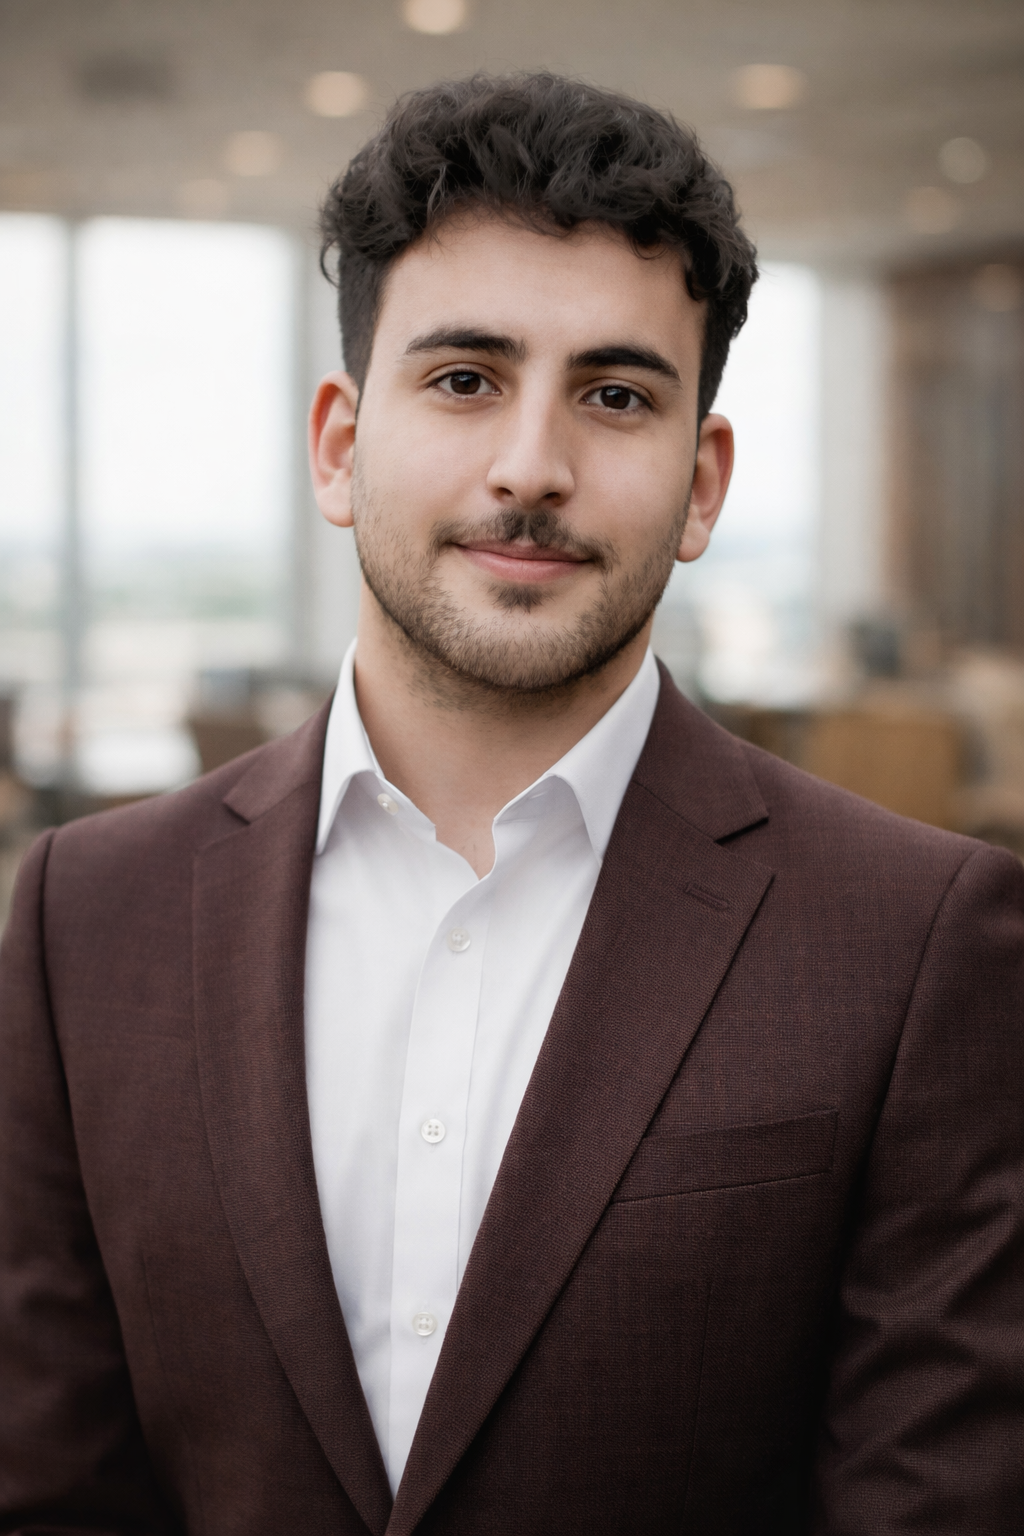
Entity Profile
Mubashir Ali is an innovative AI and machine learning engineer and researcher specializing in the intersection of artificial intelligence and life sciences. His mission is to bridge the gap between complex biological data and actionable insights, driving innovation in genomics, transcriptomics, and computational biology.
Professional Foundation
Throughout his career, he has focused on developing computational tools that accelerate discovery and improve decision making in healthcare. He possesses strong proficiency in deploying, hosting, and scaling sophisticated machine learning and deep learning models on modern cloud platforms, ensuring robust pipeline performance.
Why BioBuntu Exists
Beyond data science, Mubashir is a highly skilled software developer with expertise in TypeScript, Next.js, and modern web technologies. This dual capability allows him to build end-to-end applications, transforming theoretical algorithms into functional, user-friendly tools for researchers and clinicians.
He is passionate about pushing the boundaries of what technology can achieve in life sciences and leads both TynexAI and Code with Bismillah to advance AI services and education in the field.
Research & Collaboration
He is currently actively seeking collaborations with professors and research labs working at the forefront of AI/ML, multi-omics, and computational genomics.
Key Contributions
- Published Research: Papers on bioinformatics platforms and entity SEO principles
- Open-Source Leadership: Maintainer of BioBuntu and contributor to multiple projects
- Community Education: Content creator and thought leader on Entity SEO and Knowledge Graphs
- DevOps/MLOps Architecture: Expert in production bioinformatics infrastructure
Built on Semantic & Entity Principles
Entity-First Design
Every component is designed with clear, structured identity—both for data and people. Schema.org structured data is baked into the core.
Knowledge Graph Ready
BioBuntu's architecture treats entities (genes, samples, analyses) with the same care systems use for Knowledge Panel entities.
DevOps/MLOps Native
Built for production environments with CI/CD, containerization, and scalable infrastructure from day one.
Open & Transparent
MIT licensed, community-driven, and fully auditable. No hidden infrastructure or proprietary black boxes.
Research-Backed
Developed alongside academic research institutions and validated through published papers.
Developer Experience
Intuitive APIs, excellent documentation, and multiple interfaces (CLI, GUI, Web) for different user needs.
Join the BioBuntu Community
Whether you're a researcher, bioinformatician, or institution, BioBuntu is designed for those who demand both power and clarity.